03Building blocksHow LLM Inference Actually Works
03 · Building block
How LLM Inference Actually Works
Follow tokens through batching, prefill, KV cache, decoding, scheduling, and GPU memory constraints.Architecture map
See where the component sits in a real system.
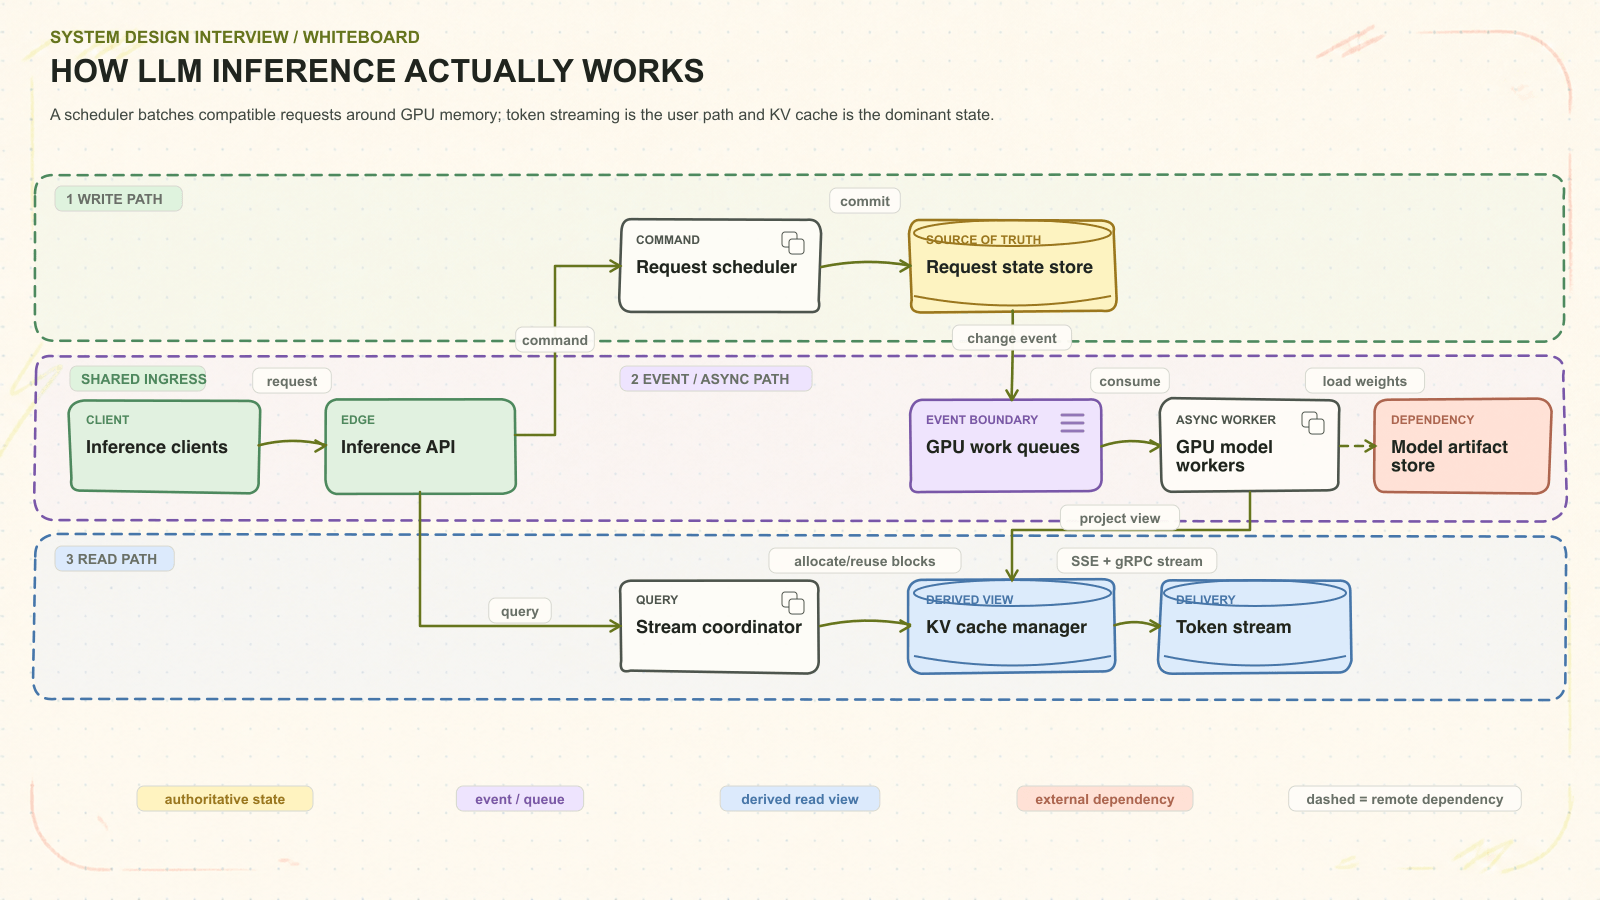
Write
Inference clients enters through Inference API. Request scheduler owns validation and commits the durable record to Request state store.
Propagate
GPU work queues separates the committed write from background work. GPU model workers can retry safely while it builds KV cache manager.
Read
Stream coordinator serves from KV cache manager, then checks authoritative state whenever freshness, policy, or correctness requires it. It also consults Model artifact store as an explicit dependency.
Say this first: A scheduler batches compatible requests around GPU memory; token streaming is the user path and KV cache is the dominant state.
Open the full whiteboard ↗Explain every boundary before adding more boxes.
A scheduler batches compatible requests around GPU memory; token streaming is the user path and KV cache is the dominant state.
Follow tokens through batching, prefill, KV cache, decoding, scheduling, and GPU memory constraints.
Prompt/decode tokens · TTFT · inter-token latency · GPU use · KV occupancy · queue time. State average and peak load, stored bytes, bandwidth or open connections, and the growth horizon before choosing a partitioning strategy.
End-to-end walkthrough
Trace the architecture in this order.
- 01
Enter and classify the request
Inference clients → Inference APIPrompt + generation params enters over HTTPS / RPC. Inference API handles identity, admission, routing, and request context; it deliberately does not own domain truth.
- 02
Validate, then cross the commit boundary
Inference API → Request scheduler → Request state storeRequest scheduler receives the command, checks invariants and retry identity, then uses commit to update Request state store. The user-visible mutation is accepted only after this boundary succeeds.
- 03
Move replayable work off the request path
Request scheduler → GPU work queues → GPU model workers → KV cache managerRequest scheduler emits publish after commit; GPU model workers uses consume and project / update to build KV cache manager. Consumers must tolerate duplicate delivery and stale retries because this path is asynchronous.
- 04
Serve reads from the right authority
Inference API → Stream coordinator → KV cache manager / Request state storeStream coordinator uses allocate/reuse blocks for the common, read-optimized path and strong read when correctness or repair requires authoritative state. The API must state the freshness promise instead of hiding it.
- 05
Contain the dependency boundary
GPU model workers → Model artifact storeload weights crosses into Model artifact store. Treat timeouts as ambiguous, use a deadline and idempotent retry or reconciliation, and keep the core state recoverable when the dependency is unavailable.
- 06
Deliver without changing the source of truth
GPU model workers → Token stream → Inference clientsGPU model workers uses fan-out; Token stream returns updates over SSE / gRPC stream. Sequence IDs, reconnect cursors, and backpressure make delivery resumable without turning a socket into durable state.
Ownership ledger
Why each box exists—and what it must defend.
| Component | Owns | Why it exists | Interviewer probe |
|---|---|---|---|
| Inference APIAuth, quota, tokenization | Identity, admission, routing | Protects the system edge and attaches trusted context before domain work begins. | Timeout budgets, quotas, regional routing |
| Request schedulerAdmission + continuous batching | Write invariants and retry identity | Serializes or conditionally applies state changes before acknowledging success. | Concurrent writes, deduplication, hot ownership |
| Request state storeQueue, owner, usage, terminal | Authoritative durable state | Provides the one record used to resolve disputes, recover, and rebuild projections. | Partition key, replication, consistency |
| GPU work queuesModel + memory class | Durable asynchronous handoff | Absorbs bursts and lets slow or optional work retry independently of the request. | Ordering key, lag, retention, dead letters |
| GPU model workersPrefill + decode loop | Replayable processing | Runs expensive, fan-out, or side-effecting work with leases and bounded retries. | Idempotency, poison work, autoscaling |
| KV cache managerPaged attention blocks | Rebuildable query state | Shapes data for the dominant reads without weakening the write-side invariant. | Freshness, versioning, rebuild time |
| Stream coordinatorOrder deltas + cancellation | Read composition and freshness policy | Chooses authoritative or derived state and returns a stable client contract. | Fan-out, cache policy, partial results |
| Model artifact storeWeights + tokenizer | External capability, not local truth | Keeps a specialized or third-party concern behind a replaceable contract. | Ambiguous timeout, circuit breaking, fallback |
| Token streamDeltas, usage, finish reason | Connection and delivery state | Separates open connections and fan-out pressure from durable domain state. | Reconnect, ordering, slow consumers |
Physical design
Name the database, shard key, indexes, and guarantees.
- Database + storage
- PostgreSQL stores request/usage state, an in-memory/Redis scheduler holds admission queues, object storage holds weights, and GPU memory holds KV blocks.
- Partitioning / sharding
- Route by model/version/GPU capability/KV locality; partition queues by model + priority while enforcing tenant fairness.
- Indexes
- Requests by tenant/time/state, unique request ID, priority/deadline heaps, and paged in-memory KV allocation.
- Replication + consistency
- Admission/usage commits are strong. Token order is per request; active KV is usually not replicated, so worker loss may create a new generation version.
- Cache, queue + recovery
- Cache weights on host SSD, page KV blocks, use continuous batching, backpressure on queue/KV pressure, and sequence terminal events.
- Capacity math
- Estimate tokens/sec, sequences, model GB, KV bytes/token/layer, TTFT, inter-token latency, bandwidth, and batch occupancy.
- Alternative rejected
- Static batches are simpler but strand capacity behind long generations; continuous batching protects utilization and tail latency.
Deep-dive candidates
Pick one risk and explain the mechanism, alternative, and cost.
Request path
Authenticate and admit the request, tokenize it, route to a compatible engine, prefill the prompt, decode tokens iteratively, detokenize, and stream events.
Tie the mechanism back to Request state store, KV cache manager, and the stated prompt/decode tokens · ttft · inter-token latency · gpu use · kv occupancy · queue time envelope.Tokens and KV cache
Each layer stores key and value tensors for prior tokens so future tokens reuse attention state; memory grows with sequence length and concurrency.
Tie the mechanism back to Request state store, KV cache manager, and the stated prompt/decode tokens · ttft · inter-token latency · gpu use · kv occupancy · queue time envelope.Prefill vs decode
Prefill processes many prompt tokens in parallel and is compute-heavy. Decode emits one token per iteration and is usually memory-bandwidth limited.
Tie the mechanism back to Request state store, KV cache manager, and the stated prompt/decode tokens · ttft · inter-token latency · gpu use · kv occupancy · queue time envelope.Failure pressure test
Show detection, containment, recovery, and evidence.
The topic-specific correctness risk
KV-cache exhaustion and long prompts create head-of-line blocking.
Track failed promises at Request state store and KV cache manager.GPU work queues or GPU model workers falls behind
Bound admission, scale on oldest-work age, retry with jitter, and isolate poison work before lag becomes unbounded.
Oldest event age · retry rate · dead-letter volume · projection freshnessRequest state store is slow or unavailable
Apply a deadline, preserve retry identity, fail over only within the stated consistency model, and reconcile any ambiguous result.
Commit p99 · timeout rate · replication lag · recovery time- Functional requirements and non-goals
- Peak traffic, storage, bandwidth, and growth
- Entities, APIs, idempotency, and pagination
- Source of truth and consistency promise
- Partition key, replicas, caches, and hot spots
- Retries, backpressure, failover, and reconciliation
- Latency, saturation, correctness, and recovery metrics
- Security, migration, cost, and multi-region evolution
Read the solid request path first, stop at the source of truth, then follow the dashed event path into workers and rebuildable read models. Every arrow names a contract you should be ready to defend.
- 01
API — Validates model and limits Define the output contract before moving to the next owner.
- 02
Router — Selects a replica Define the output contract before moving to the next owner.
- 03
Admission queue — Protects GPU capacity Define the output contract before moving to the next owner.
- 04
Prefill batch — Processes prompts Define the output contract before moving to the next owner.
- 05
KV cache — Retains attention state Define the output contract before moving to the next owner.
- 06
Decode scheduler — Interleaves generation Define the output contract before moving to the next owner.
- 07
Stream — Returns tokens and usage Confirm the result and emit the evidence needed to reconcile it.
Lesson spine
What you need to understand.
LLM serving is a stateful scheduling problem shaped by model weights, KV-cache memory, open streams, and two different compute phases.
Request path
Authenticate and admit the request, tokenize it, route to a compatible engine, prefill the prompt, decode tokens iteratively, detokenize, and stream events.
Tokens and KV cache
Each layer stores key and value tensors for prior tokens so future tokens reuse attention state; memory grows with sequence length and concurrency.
Prefill vs decode
Prefill processes many prompt tokens in parallel and is compute-heavy. Decode emits one token per iteration and is usually memory-bandwidth limited.
Continuous batching
At every decode step, remove completed sequences and admit new ones whose KV memory fits, preventing long generations from holding an entire static batch.
Scale the tiers
Gateways scale with open connections, routers need live queue and cache pressure, and GPU fleets scale on queue delay and KV utilization—not CPU.
Latency metrics
Separate time to first token, inter-token latency, total generation time, queue time, and tokens per second.
Before the boxes
Frame the decision.
What must work
Follow tokens through batching, prefill, KV cache, decoding, scheduling, and GPU memory constraints.
What changes the design
Prompt/decode tokens · TTFT · inter-token latency · GPU use · KV occupancy · queue time
What owns the truth
Identify the component that commits authoritative state, then separate synchronous confirmation from derived work.
What stays simple
Do not add global coordination, multi-region writes, or a specialized store until a requirement earns the complexity.
Decision table
Make the trade-offs explicit.
| Decision | Defensible position | Cost to acknowledge |
|---|---|---|
| Primary mechanism | Large batches maximize throughput; continuous batching protects time to first token and fairness. | The stronger guarantee usually adds coordination, latency, state, or operational work. |
| Sync vs. async | Keep only correctness-critical confirmation synchronous. Move derived views, notifications, analytics, and cleanup behind a durable boundary. | Async work needs idempotency, lag monitoring, replay, and a product definition for partial completion. |
| Simple vs. scaled | Begin with one logical owner and a clear API. Partition or replicate only the resource proven to be the first bottleneck. | Migration requires stable identities, versioned contracts, backfill, and a rollback path. |
Failure review
Design the recovery path.
Topic-specific risk
KV-cache exhaustion and long prompts create head-of-line blocking.
ResponsePersist enough identity and state to distinguish retry, resume, compensation, and operator repair.
Dependency timeout
A timeout is ambiguous: the remote side may have failed, succeeded, or still be running.
ResponseUse deadlines, bounded backoff with jitter, idempotency keys, and a status or reconciliation path.
Overload or skew
Average capacity can look healthy while a tenant, key, partition, region, or expensive request saturates one owner.
ResponseExpose queue depth and hot-key share, apply backpressure, isolate tenants, and degrade optional work before correctness.
Evidence + level bar
Prove the design can be operated.
Health of the promise
Measure user-visible latency or freshness, correctness drift, saturation, retry volume, and time to recover. Alert on the failed promise—not only CPU.
Complete and clear
Finish the happy path, identify the state owner, choose reasonable building blocks, and explain one scale mechanism.
Trade-offs and failure
Separate read and write paths, define consistency, explain partitioning, and make duplicate or partial failure safe.
Evolution and operations
Discuss multi-region boundaries, migration, tenant isolation, capacity, observability, and how the architecture changes over time.
Interview language
Open the deep dive with a claim.
“For How LLM Inference Actually Works, the decision I want to make explicit is this: Large batches maximize throughput; continuous batching protects time to first token and fairness. I’ll trace the state-changing path first, show where the result becomes durable, then test the design against the highest-risk failure and our target scale.”
08 · Retrieval check
Can you defend it without the page?
- For How LLM Inference Actually Works, where is the correctness boundary and which failure would you test first?
- Which component owns committed truth, and what event or response proves the commit?
- Where is the first scaling or coordination bottleneck under the stated envelope?
- What happens after an ambiguous timeout or duplicate operation?
- Which complexity would you remove at one hundredth of the scale?