04QuestionsDistributed file system
04 · Worked prompt
Distributed file system
Design metadata, chunk placement, replication, checksums, repair, and namespace consistency.What a passing answer must show
100 points · 45 minutes
- 20pts
Scope the problem
0–5 minPrioritize the core flows, state the scale, and name the non-goals.
- 15pts
Define contracts
5–10 minIdentify durable entities, APIs, idempotency, and the source of truth.
- 30pts
Complete the diagram
10–25 minTrace one write path and one read path. Label the commit boundary and async work.
- 20pts
Lead one deep dive
25–38 minChoose the highest-risk trade-off and explain the mechanism, alternative, and cost.
- 15pts
Prove reliability
38–45 minWalk a failure, recovery, metric, bottleneck, and evolution path.
One complete box-and-arrow design
Design metadata, chunk placement, replication, checksums, repair, and namespace consistency.
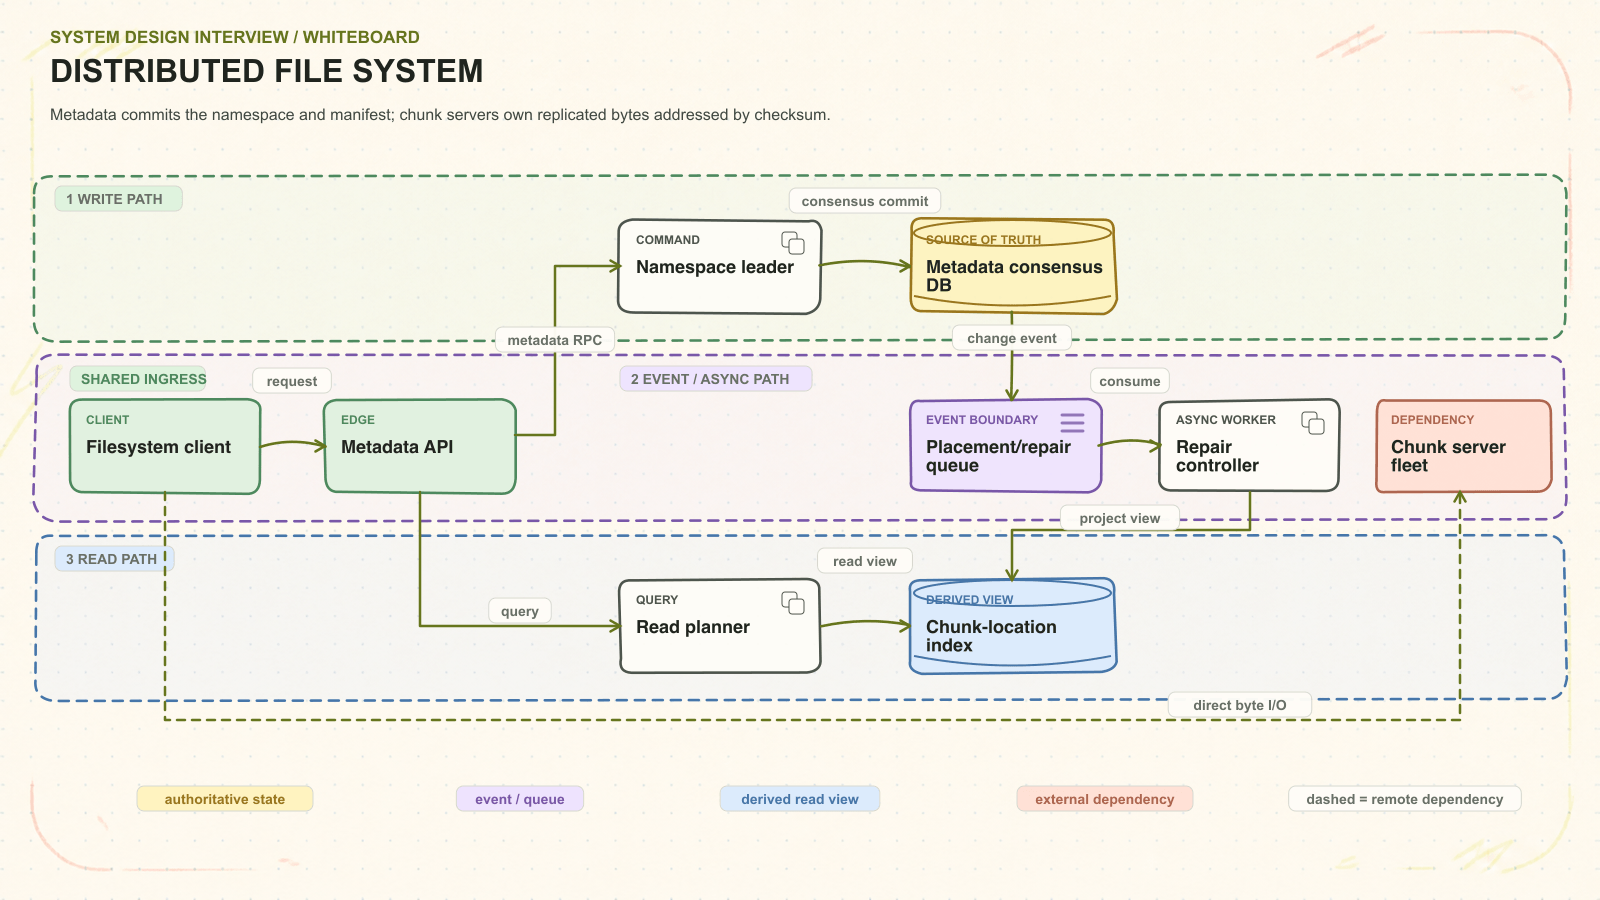
Write
Filesystem client enters through Metadata API. Namespace leader owns validation and commits the durable record to Metadata consensus DB.
Propagate
Placement/repair queue separates the committed write from background work. Repair controller can retry safely while it builds Chunk-location index.
Read
Read planner serves from Chunk-location index, then checks authoritative state whenever freshness, policy, or correctness requires it. It also consults Chunk server fleet as an explicit dependency.
Say this first: Metadata commits the namespace and manifest; chunk servers own replicated bytes addressed by checksum.
Open the full whiteboard ↗Explain every boundary before adding more boxes.
Metadata commits the namespace and manifest; chunk servers own replicated bytes addressed by checksum.
Design metadata, chunk placement, replication, checksums, repair, and namespace consistency.
Petabytes · billions objects · large transfers · extreme durability. State average and peak load, stored bytes, bandwidth or open connections, and the growth horizon before choosing a partitioning strategy.
End-to-end walkthrough
Trace the architecture in this order.
- 01
Enter and classify the request
Filesystem client → Metadata APIOpen, upload, read range enters over HTTPS / RPC. Metadata API handles identity, admission, routing, and request context; it deliberately does not own domain truth.
- 02
Validate, then cross the commit boundary
Metadata API → Namespace leader → Metadata consensus DBNamespace leader receives the metadata RPC, checks invariants and retry identity, then uses consensus commit to update Metadata consensus DB. The user-visible mutation is accepted only after this boundary succeeds.
- 03
Move replayable work off the request path
Namespace leader → Placement/repair queue → Repair controller → Chunk-location indexNamespace leader emits publish after commit; Repair controller uses consume and project / update to build Chunk-location index. Consumers must tolerate duplicate delivery and stale retries because this path is asynchronous.
- 04
Serve reads from the right authority
Metadata API → Read planner → Chunk-location index / Metadata consensus DBRead planner uses optimized read for the common, read-optimized path and strong read when correctness or repair requires authoritative state. The API must state the freshness promise instead of hiding it.
- 05
Contain the dependency boundary
Filesystem client → Chunk server fleetdirect byte I/O crosses into Chunk server fleet. Treat timeouts as ambiguous, use a deadline and idempotent retry or reconciliation, and keep the core state recoverable when the dependency is unavailable.
Ownership ledger
Why each box exists—and what it must defend.
| Component | Owns | Why it exists | Interviewer probe |
|---|---|---|---|
| Metadata APIAuth + path resolution | Identity, admission, routing | Protects the system edge and attaches trusted context before domain work begins. | Timeout budgets, quotas, regional routing |
| Namespace leaderReserve + commit manifest | Write invariants and retry identity | Serializes or conditionally applies state changes before acknowledging success. | Concurrent writes, deduplication, hot ownership |
| Metadata consensus DBInodes + manifests | Authoritative durable state | Provides the one record used to resolve disputes, recover, and rebuild projections. | Partition key, replication, consistency |
| Placement/repair queueUnder-replicated chunks | Durable asynchronous handoff | Absorbs bursts and lets slow or optional work retry independently of the request. | Ordering key, lag, retention, dead letters |
| Repair controllerCopy, checksum, rebalance | Replayable processing | Runs expensive, fan-out, or side-effecting work with leases and bounded retries. | Idempotency, poison work, autoscaling |
| Chunk-location indexHealthy replica map | Rebuildable query state | Shapes data for the dominant reads without weakening the write-side invariant. | Freshness, versioning, rebuild time |
| Read plannerManifest + replica choice | Read composition and freshness policy | Chooses authoritative or derived state and returns a stable client contract. | Fan-out, cache policy, partial results |
| Chunk server fleetReplicated immutable chunks | External capability, not local truth | Keeps a specialized or third-party concern behind a replaceable contract. | Ambiguous timeout, circuit breaking, fallback |
Physical design
Name the database, shard key, indexes, and guarantees.
- Database + storage
- A Raft/Spanner/Cockroach-style metadata store owns namespace and manifests; replicated chunk servers or object storage own immutable byte chunks.
- Partitioning / sharding
- Partition the namespace by volume or directory subtree; place chunks by rendezvous hash across failure domains. Clients transfer bytes directly.
- Indexes
- Unique (parent_inode, name), manifest by file_id/version, chunk locations by chunk_id, and an under-replicated priority index.
- Replication + consistency
- Metadata commits through quorum. Chunks use three replicas or erasure coding; cached locations are valid only under a manifest version/lease.
- Cache, queue + recovery
- Repair, rebalancing, scrub, and garbage collection use durable queues. A file is visible only after a complete manifest commits.
- Capacity math
- Estimate files, namespace ops/sec, p50/p99 file size, chunk size, aggregate throughput, metadata bytes/file, and repair bandwidth.
- Alternative rejected
- Database BLOBs simplify transactions but destroy metadata latency and replication cost; separate immutable bytes from strong metadata.
Deep-dive candidates
Pick one risk and explain the mechanism, alternative, and cost.
Metadata sharding
Partition by stable directory or inode ownership and handle cross-shard rename as an explicit transaction
Path strings are poor stable shard keysDurability
Place replicas across failure domains and repair from periodic integrity scans
Replication count alone does not prove durabilityAtomic visibility
Expose a file only after a conditional manifest commit references verified chunks
Bytes and metadata must not become visible independentlyFailure pressure test
Show detection, containment, recovery, and evidence.
Storage node loss
Read another replica and enqueue priority repair
under-replicated bytes and repair ageClient abandons upload
Expire session and garbage-collect unreferenced chunks
orphan bytesMetadata leader loss
Fail over under a fenced epoch and replay durable log
namespace recovery time- Functional requirements and non-goals
- Peak traffic, storage, bandwidth, and growth
- Entities, APIs, idempotency, and pagination
- Source of truth and consistency promise
- Partition key, replicas, caches, and hot spots
- Retries, backpressure, failover, and reconciliation
- Latency, saturation, correctness, and recovery metrics
- Security, migration, cost, and multi-region evolution
A four-part talk track
- Scope
“I’ll prioritize create, read, list, rename, and delete paths and upload and download very large files.”
- Scale
“The design changes around petabytes · billions objects · large transfers · extreme durability.”
- Decision
“Immutable object semantics scale simply; mutable hierarchy needs stronger metadata coordination.”
- Risk
“The first failure I want to pressure-test is: A metadata commit that outlives only some chunks exposes corrupt files.”
Reference details
Open these only after you can explain the diagram above without reading.
01Requirements and state lifecycle4 requirements
- Create, read, list, rename, and delete paths
- Upload and download very large files
- Survive node and rack loss without corrupt data
- Scale namespace and background repair independently
Each transition must be durable, observable, and safe to retry.
02Data model and APIs4 entities · 4 interfaces
Core entities
inode_id, parent_id, name, type, versionOwner: Metadata serviceinode_id, ordered_chunks, size, checksumOwner: Metadata servicechunk_id, node_id, checksum, stateOwner: Chunk managersession_id, target_path, parts, expiryOwner: Upload coordinatorExternal interfaces
/v1/uploadsReserve a target path and multipart plan
/v1/uploads/{id}/parts/{n}Transfer a checksummed immutable chunk
/v1/uploads/{id}/commitAtomically publish the completed manifest
/v1/files/{path}Resolve manifest and signed replica reads
03Deep dives and trade-offsChoose one
Metadata sharding
Partition by stable directory or inode ownership and handle cross-shard rename as an explicit transaction
Path strings are poor stable shard keysDurability
Place replicas across failure domains and repair from periodic integrity scans
Replication count alone does not prove durabilityAtomic visibility
Expose a file only after a conditional manifest commit references verified chunks
Bytes and metadata must not become visible independently04Failures, recovery, and evidence3 scenarios
Storage node loss
Read another replica and enqueue priority repair
under-replicated bytes and repair ageClient abandons upload
Expire session and garbage-collect unreferenced chunks
orphan bytesMetadata leader loss
Fail over under a fenced epoch and replay durable log
namespace recovery time05What makes the answer seniorInterviewer signals
- Draw metadata and byte paths separately
- The manifest commit is the key correctness boundary
- Discuss directory operations, not only S3-style immutable objects
- Primary trade-off: Immutable object semantics scale simply; mutable hierarchy needs stronger metadata coordination.
Can you redraw it from memory?
- Name the source of truth.
- Trace the write and read paths.
- Defend one trade-off.
- Recover from one failure.